Hands-on demos of Squirro Neo, GraphRAG and our agents. No sign-up, no sales call. Try Them Now

Classifier

Auto-Classify Every Document to Your Own Taxonomy.

The Squirro Classifier tags each document as it arrives, with the concepts your experts keep in Squirro Graphite. When it is unsure, a person decides. New terms wait for an editor.
Trusted by Industry Leaders
library of congress OCBC Bank Zwickroell Security Benefit Henkel Siemens Bertelsmann pavlov media long beach container terminal Deutsche Bundesbank Candriam IDB Invest Bühler logo swissrockets Customer Logo

“I remember the moment I saw this working and thinking: this is it. After years of looking, this was the first time I saw something that could actually solve the problem. Not a workaround, not a partial answer, but a real solution.”

Melinda Geist Taxonomy practitioner with decades inside global technology companies After a four-week trial of the Squirro Classifier. Watch the webinar with Melinda Geist

Every Document Tagged on Arrival.

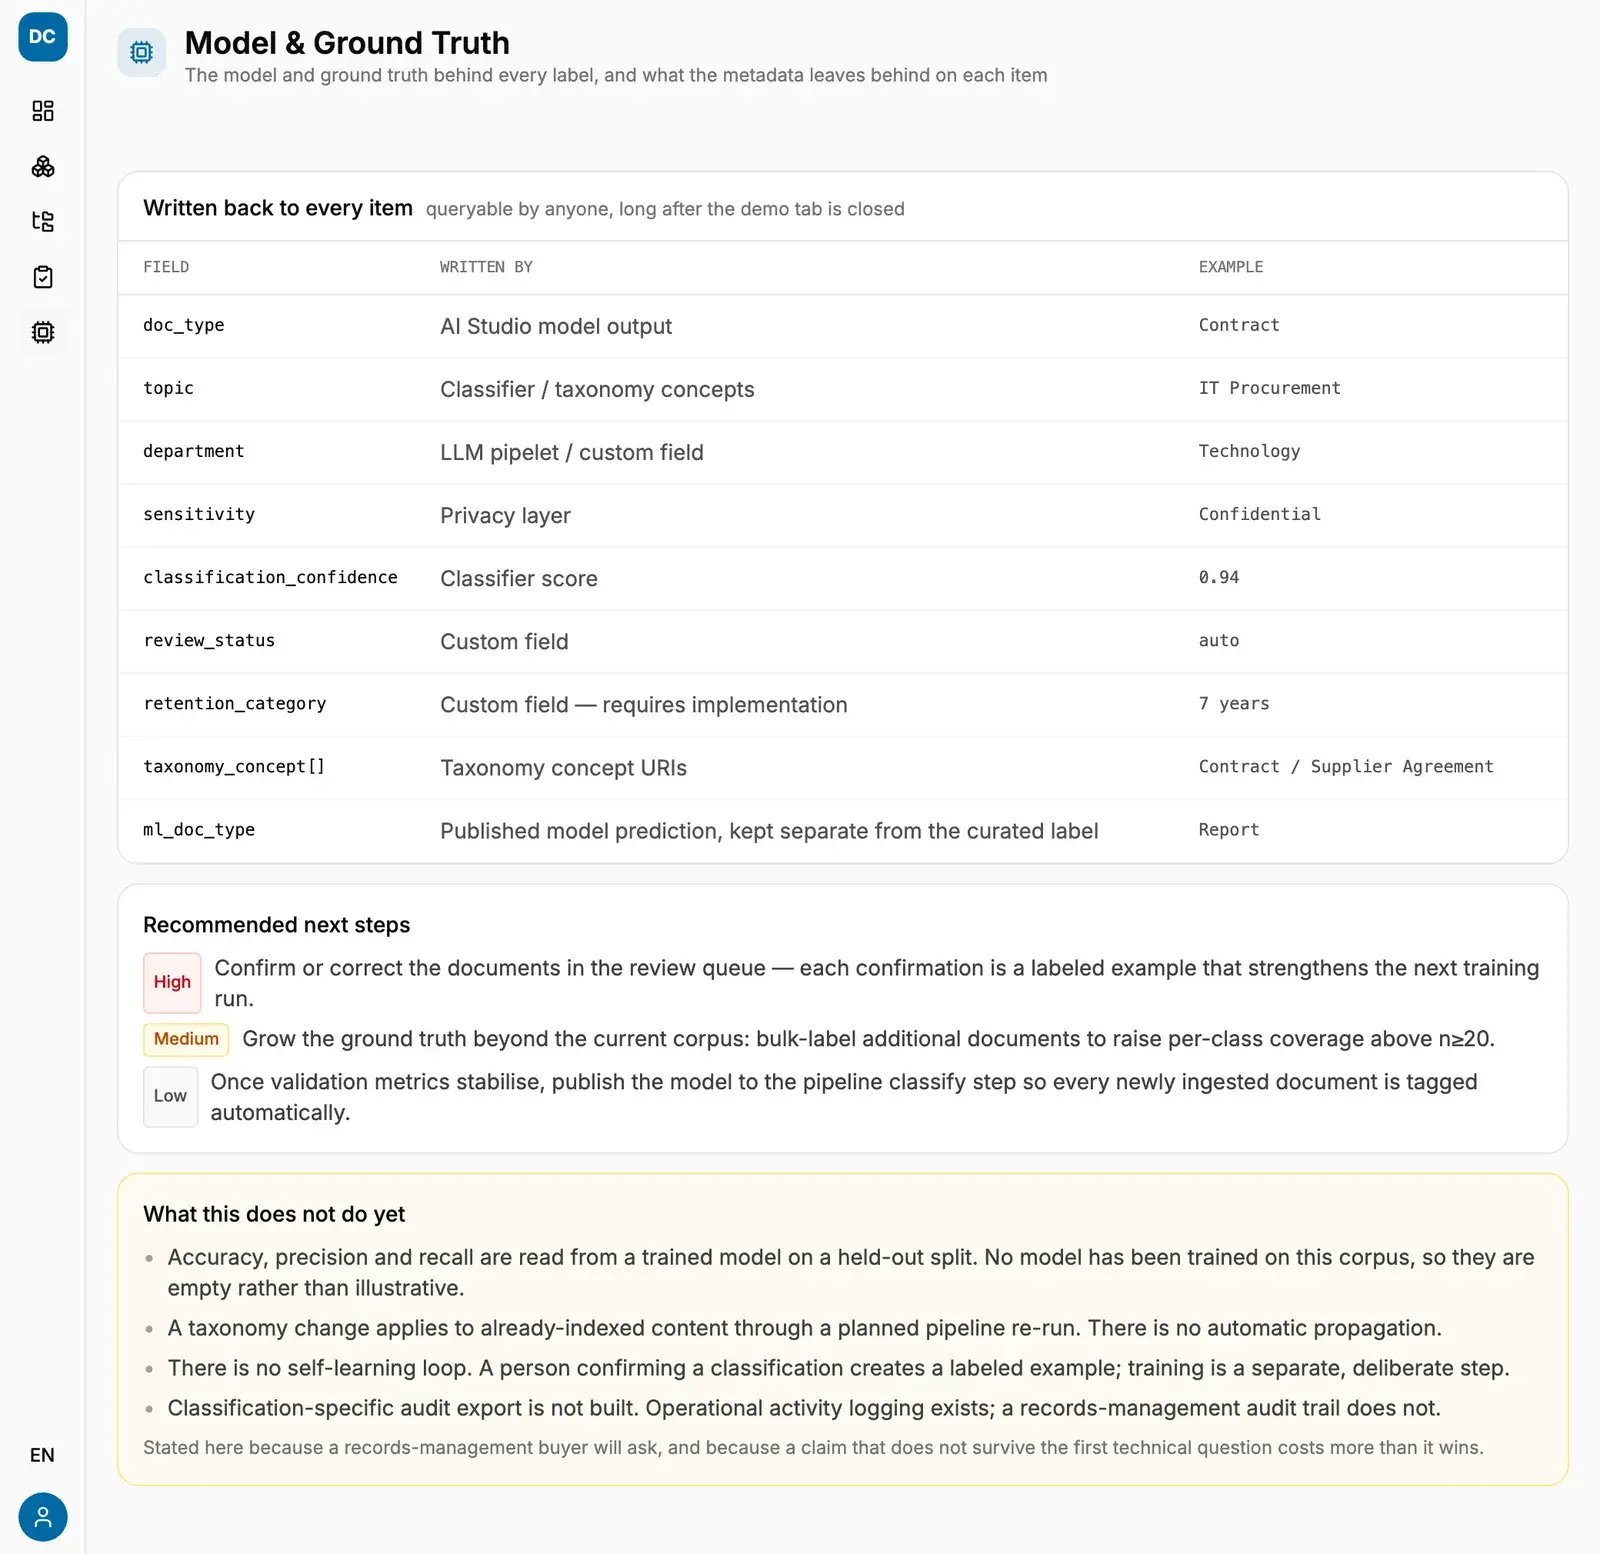
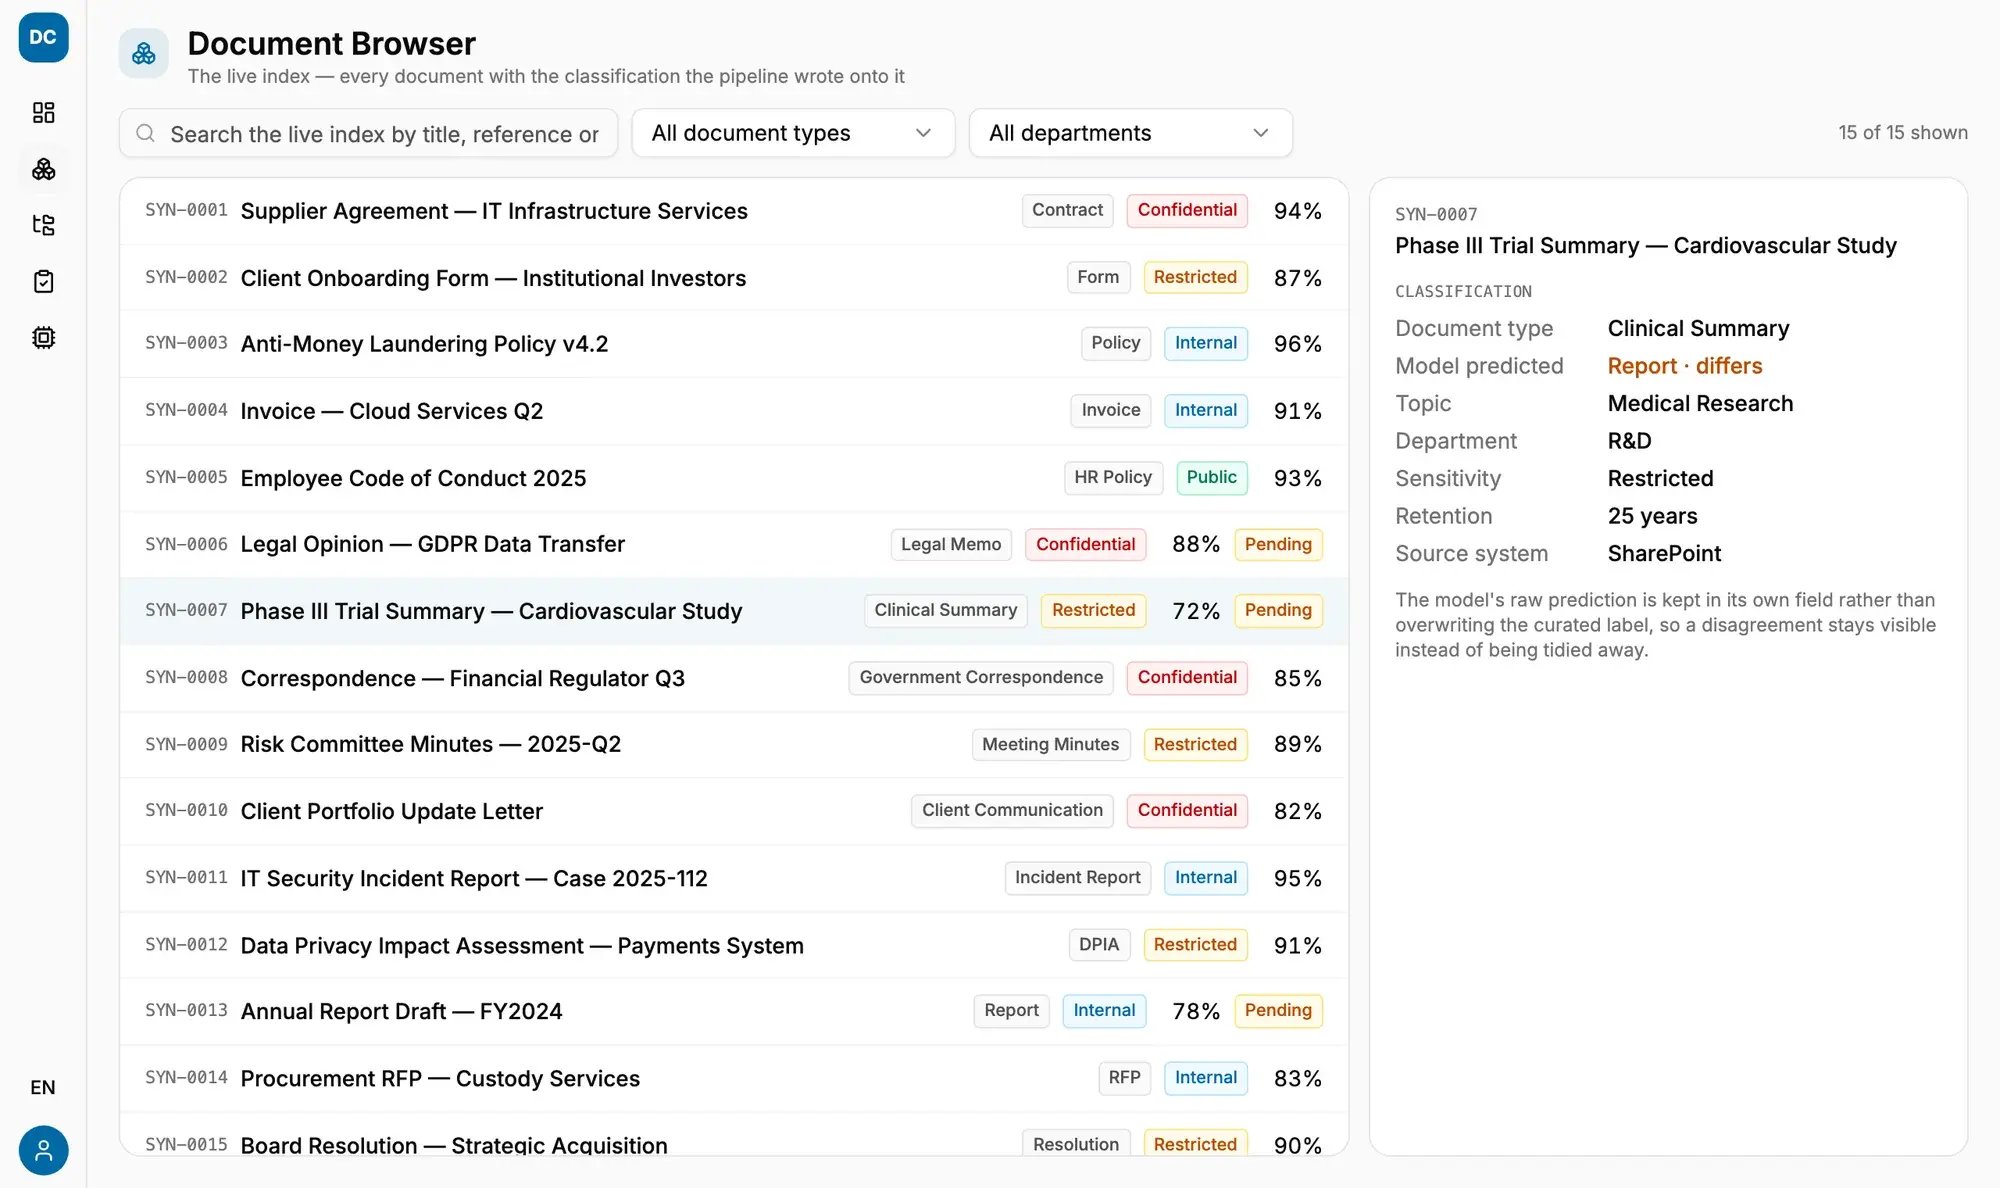
As connectors bring content in, the Classifier writes the document type and its topics onto each item, with a confidence score, before anyone opens it. Fields such as department, sensitivity, or retention can be added.

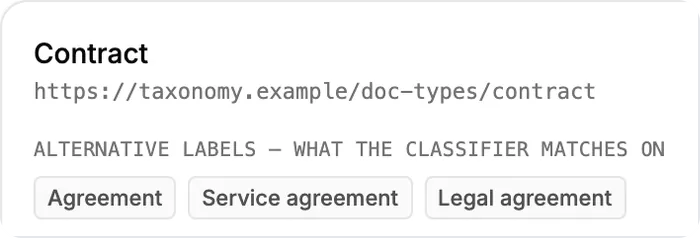
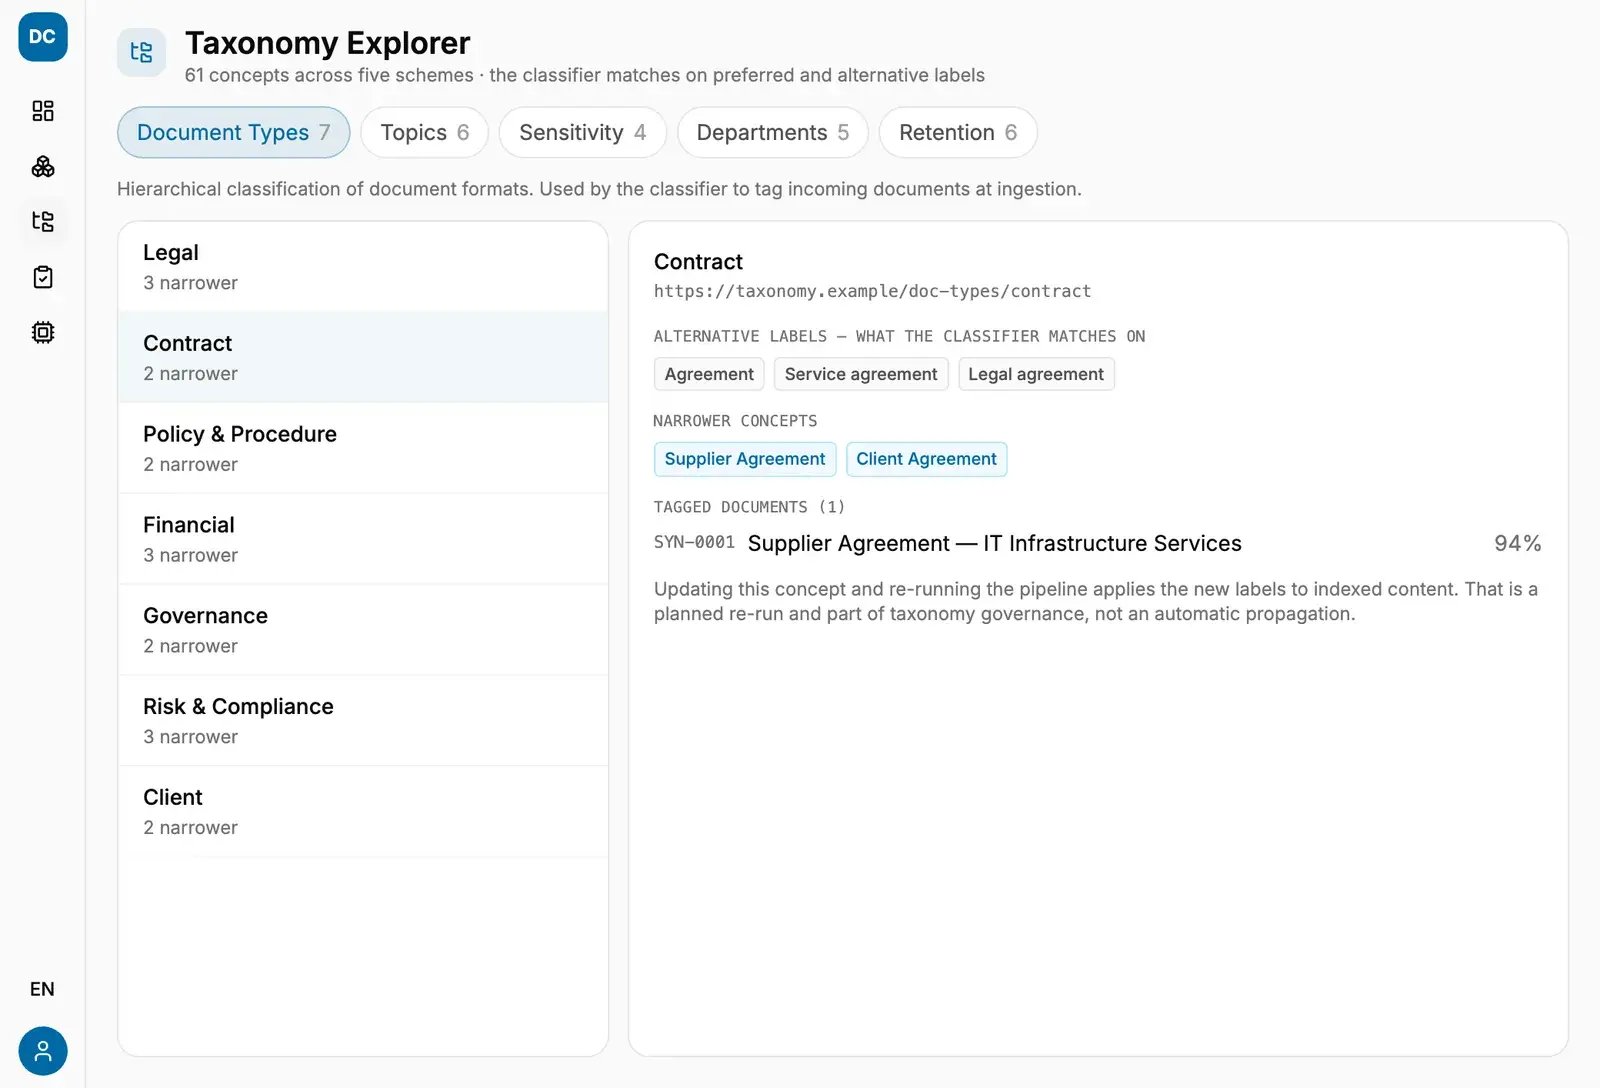
It tags with the concepts your taxonomists designed and matches on their alternative labels, so a document that says “service agreement” still lands under Contract.

Explore Squirro Graphite

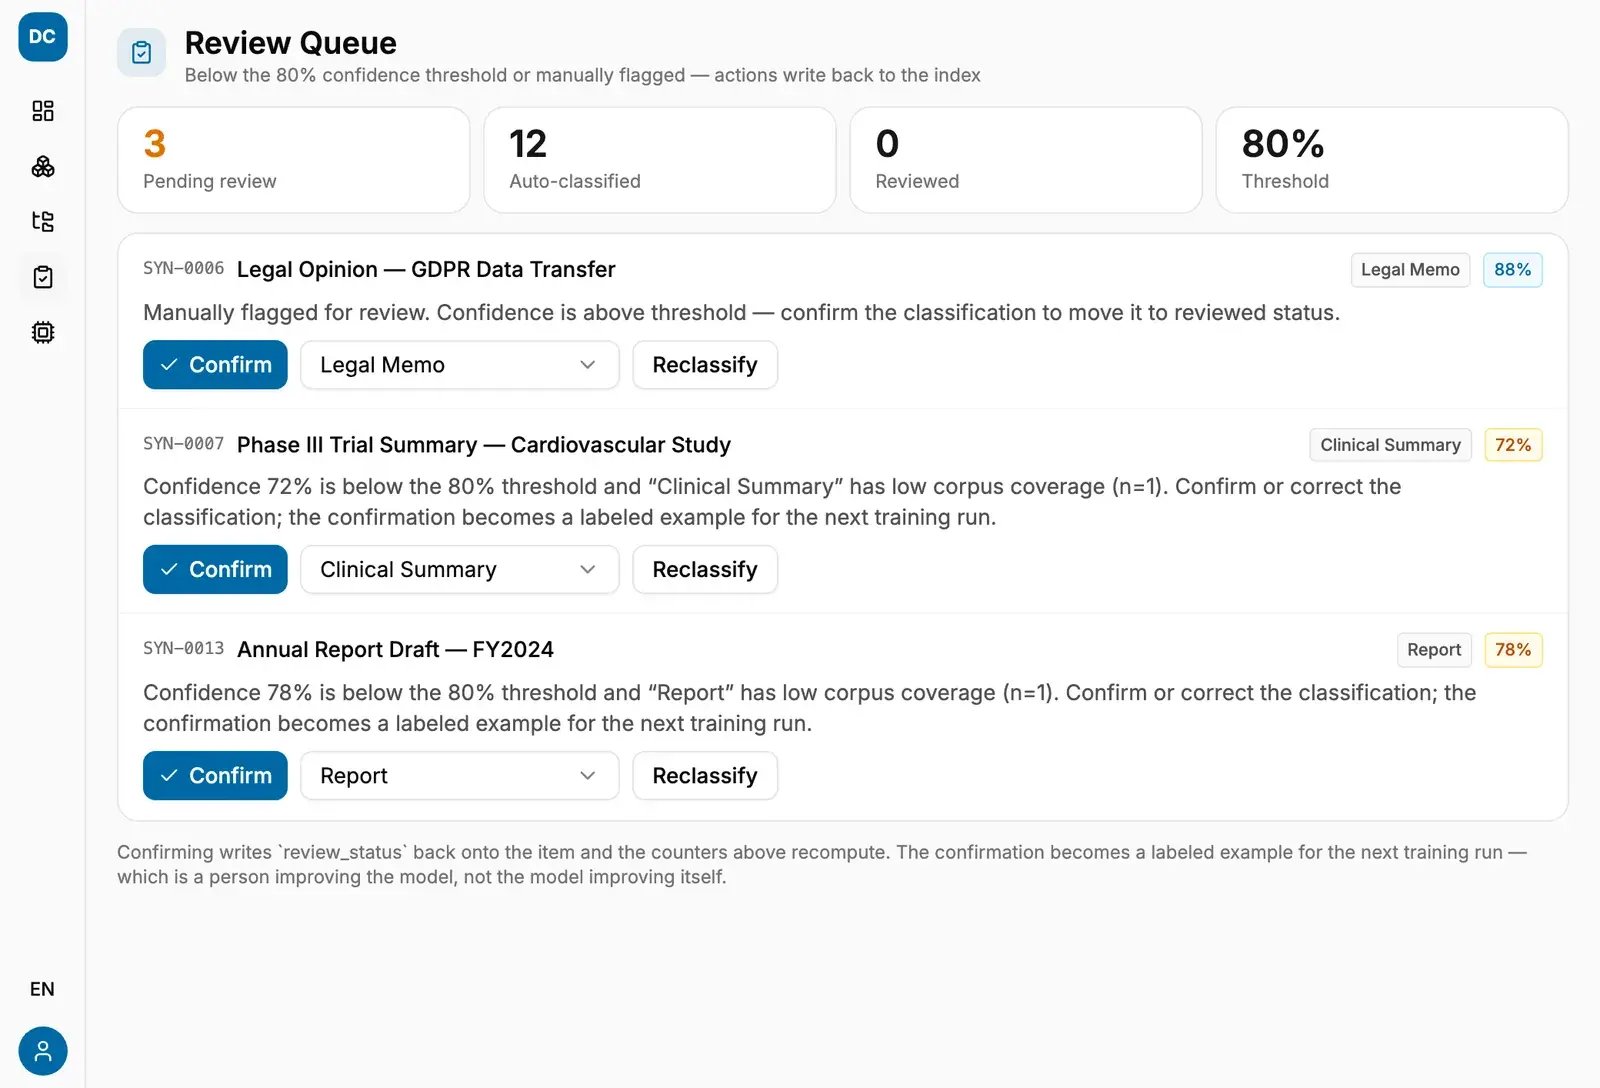
Below the confidence threshold, a document goes to a review queue with the reason printed beside it. Each confirmation becomes a labeled example for the next training run.

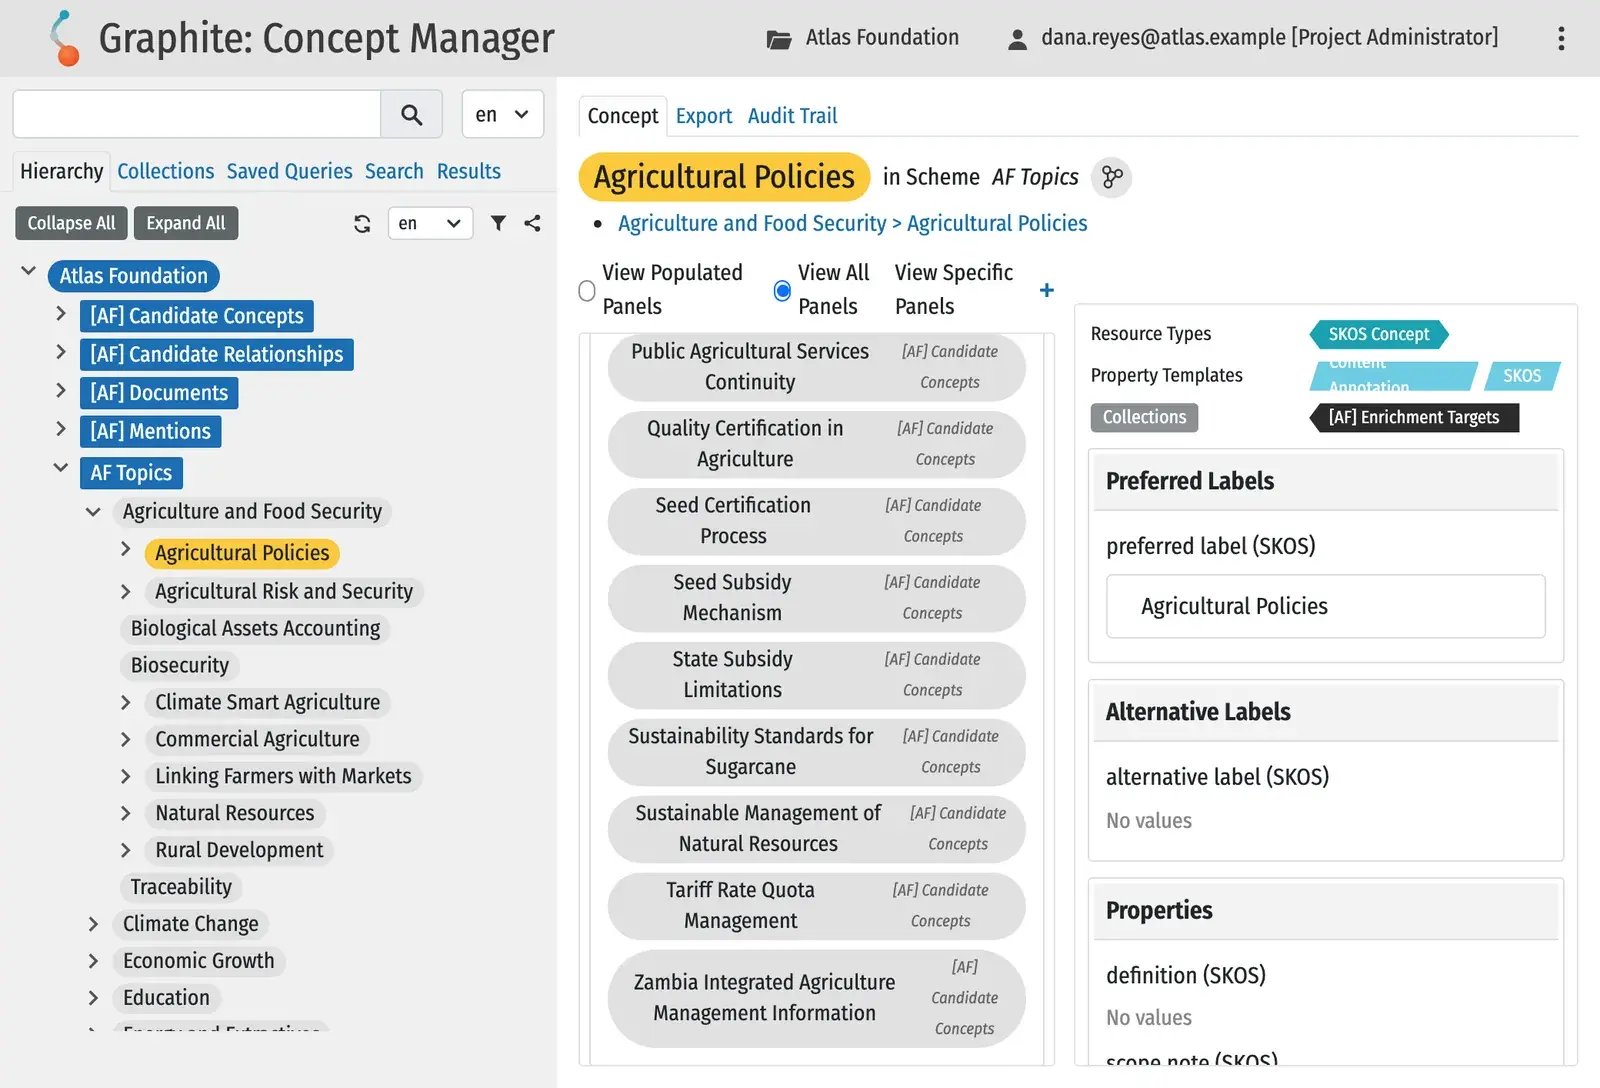
Terms your taxonomy does not have yet arrive in Graphite as candidates, kept apart from the approved hierarchy until an editor accepts, merges, or withdraws each one.

Explore Knowledge Graphs
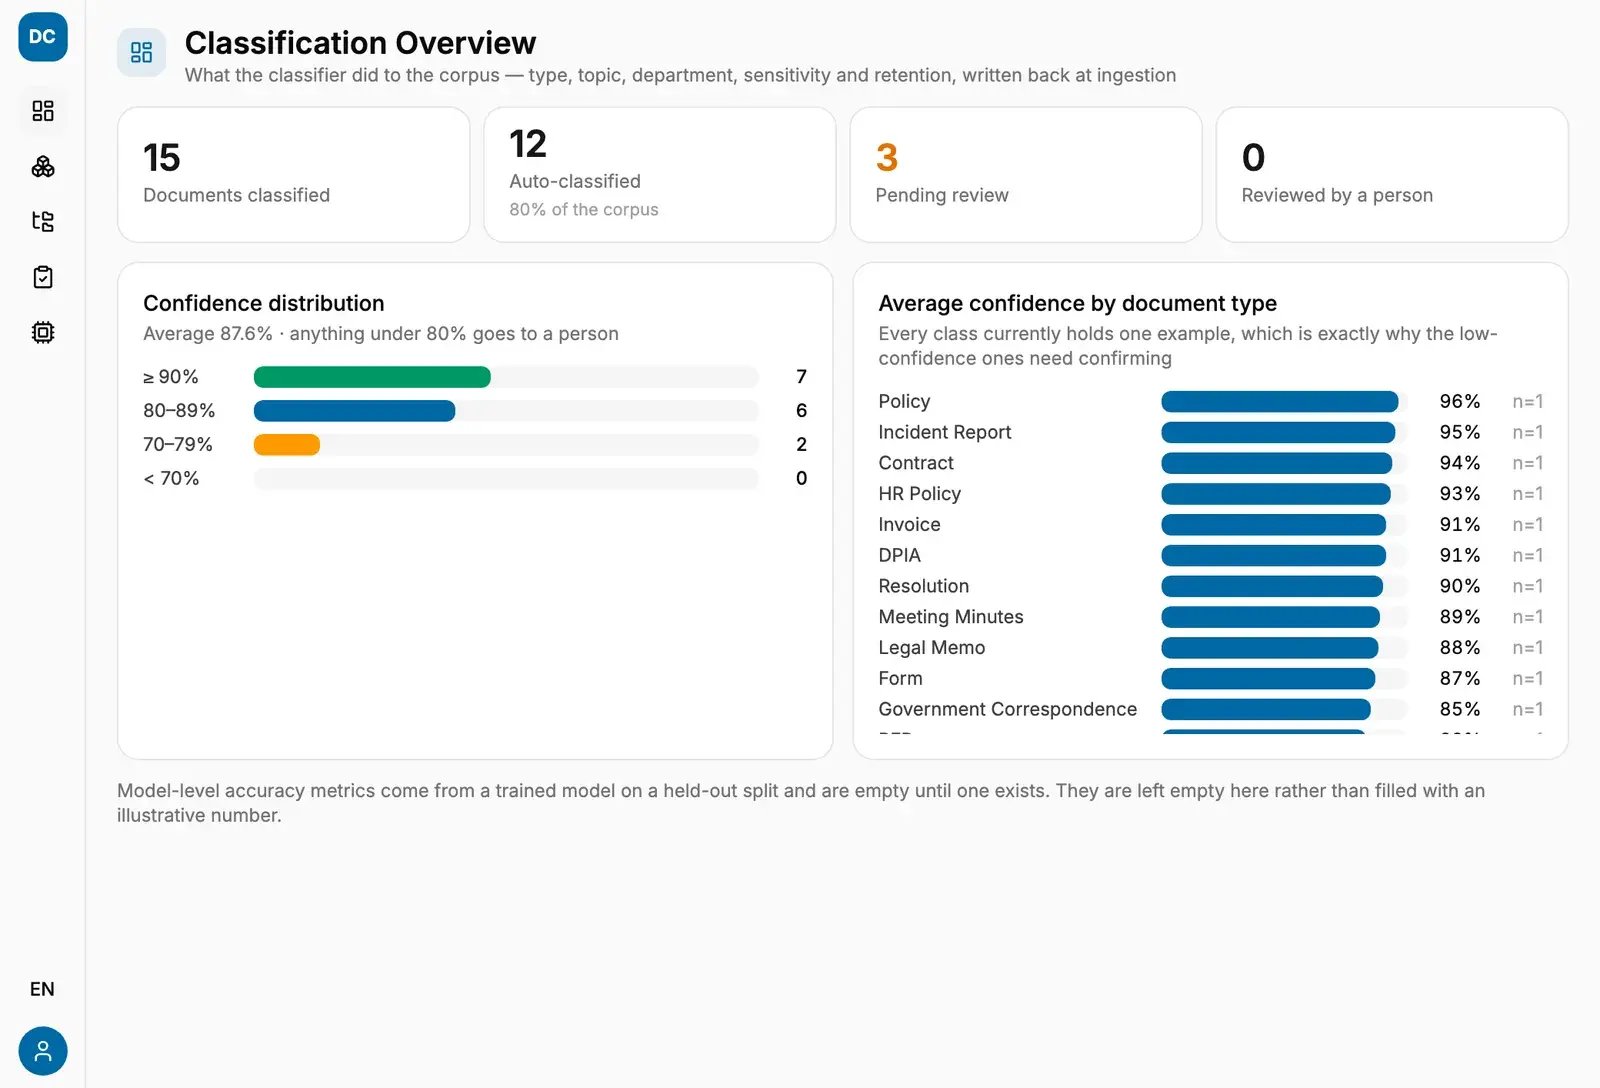
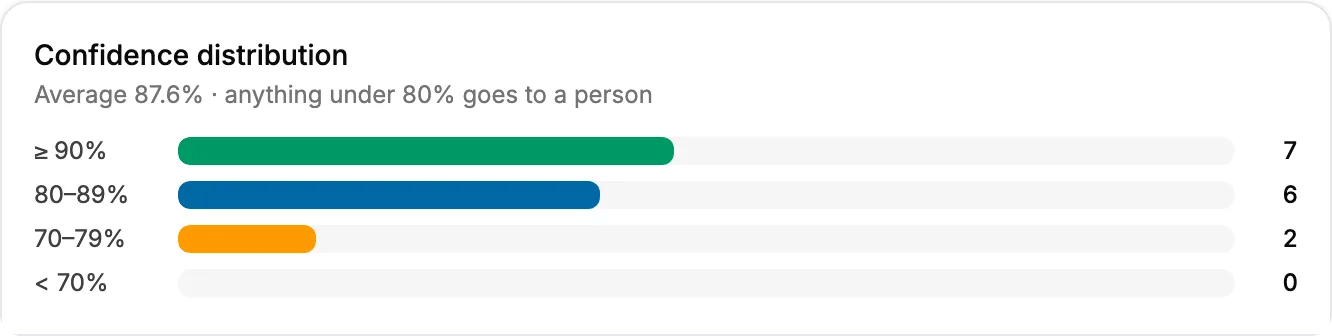
The Classification Overview: documents classified, auto-classified, and pending review, the confidence distribution with everything under 80% routed to a person, and average confidence by document type
Model and Ground Truth: the fields written back to every item and what writes each one, the recommended next steps, and what the classification does not do yet

Metadata That Stays With Every Item in Every System.

What the Classifier writes stays on the item, where any search, report, or agent can use it. The model’s own prediction is kept beside the curated label, so a disagreement stays visible instead of being tidied away.

  • Topics are concept URIs from your taxonomy
  • Search filters by what documents are about, from the same tags

Frequently Asked Questions.

Do we need Squirro Graphite?

Squirro Classifier tags each document with concepts from your taxonomy, which your experts keep and approve in Squirro Graphite. If your taxonomy lives in another tool today, Graphite imports it from standard files.

Does it learn on its own?

No. When a reviewer confirms or corrects a document, it becomes a labeled example. Training on those examples is a step your team runs and checks before the new model is published.

What happens to documents we already have?

New documents are tagged as they arrive. Documents already indexed, and every document after a taxonomy change, are tagged by a planned re-run of the pipeline.

Is this the same as data classification for security?

No. Security tools label data by sensitivity for access and loss prevention. The Classifier tags documents by what they are about, in your own vocabulary. A sensitivity field can sit beside its tags, written by the platform’s privacy layer.

Where does it run?

The Classifier is part of the Squirro Platform, in Squirro Cloud, your VPC, or your premises. See what runs where.