INGESTION
Documents ingested from any source
SharePoint, OpenText, network drives, email archives. New documents classified on arrival. Existing content processed in bulk.
Information Management · Banking · Government · Healthcare · Legal
Untagged documents pile up. Manual teams fall behind. Self-tagging gets abandoned. Squirro classifies every document accurately and automatically at any scale, from the moment it enters your organization.
Trusted by Industry Leaders
Measurable Impact
Evidence in Action
How it works
Manual tagging teams fall behind by design: content arrives faster than people can process it. Squirro steps in at ingestion, applying a consistent enterprise taxonomy automatically across every document, every system, every day. The backlog stops growing. The governance starts working.
INGESTION
SharePoint, OpenText, network drives, email archives. New documents classified on arrival. Existing content processed in bulk.
TAXONOMY
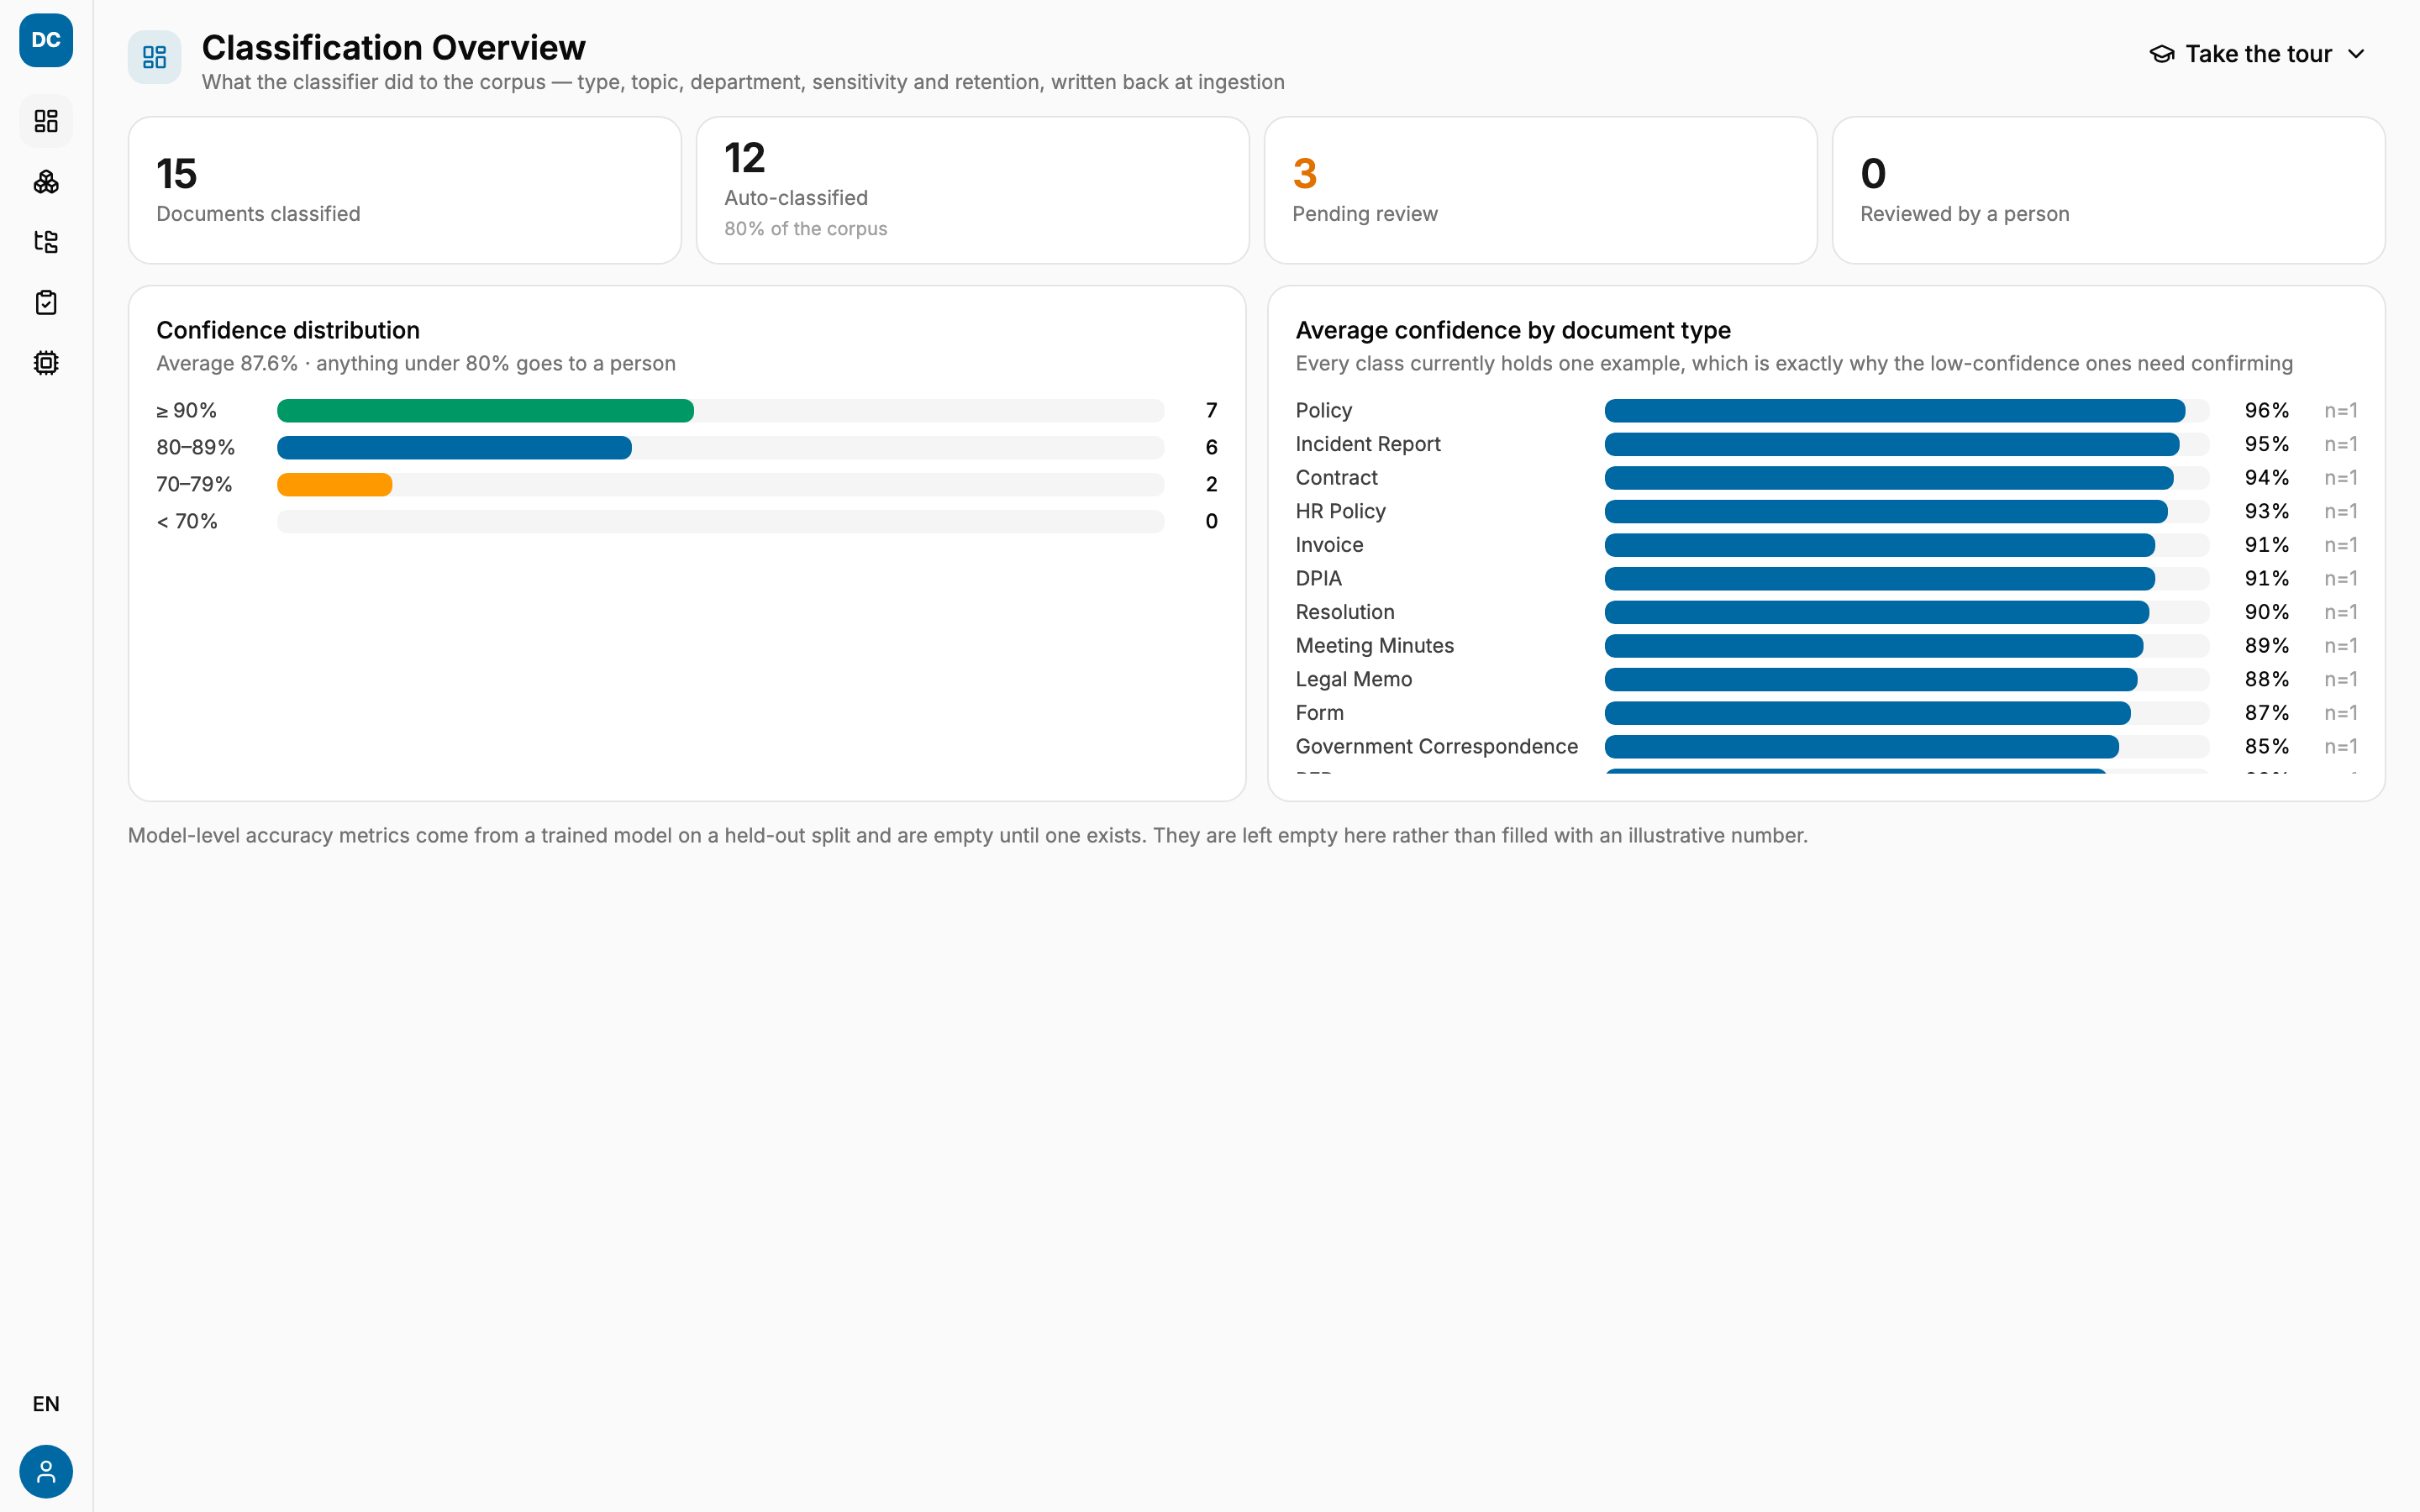
Every document tagged by type, topic, department, and sensitivity. No inconsistency between departments.
QUALITY
Self-learning engine improves with every document processed. Taxonomy updates propagate automatically. Admin dashboard shows quality across the entire corpus.
GOVERNANCE
Correctly classified documents are immediately searchable and correctly retained. When a regulator asks, the answer is available in minutes.
doc_typeAI Studio model outputContract
topicClassifier / taxonomy conceptsIT Procurement
departmentLLM pipelet / custom fieldTechnology
sensitivityPrivacy layerConfidential
classification_confidenceClassifier score0.94
review_statusCustom fieldauto
taxonomy_concept[]Taxonomy concept URIsContract / Supplier Agreement
Integrations
Break down data silos and integrate all of your existing data, creating a single source of truth.
Your Expansion Path
Classification is the foundation. Everything built on top – search, compliance, governance, migration – gets better as the taxonomy matures.
Automatic classification, Synaptica-powered taxonomy, self-learning accuracy, full audit trail. Live in 4–8 weeks.
Classification feeds directly into unified semantic search, making documents findable across every repository, by any dimension.
Retention categories applied automatically. Sensitive content identified and access-controlled. Regulatory requirements met without manual intervention.
A connected content layer spanning classification, search, governance, and knowledge graph enrichment, where every document is organized, findable, and governed from the moment it arrives.
Our Platform
Most enterprises rebuild the same plumbing for every AI project — connectors, governance, retrieval, audit. Squirro builds it once. You extend it.
One Platform. Limitless Workflows. Ready to Deploy.
Ready to Deploy
Document taxonomy and classification, enterprise search unification, and automated content governance each create friction differently in every org. We work with organizations to map the most strategic path to value and to deploy quickly where the friction is sharpest.
Share your details with us to discover the use case, discuss how it fits your stack, or explore a deployment.